Release Readiness, independently verifiable

Technical diligence,
underwritten by evidence.

Point Comreadiness at any repository. In under an hour it returns an evidence-backed Release Readiness Index: every finding cited to the line, every control attested, and the verdict sealed in a certificate any counterparty can independently verify.

< 1 hr
to first scored report
10
weighted domains
Signed
independently verifiable
Read-only
no clone · snippets only
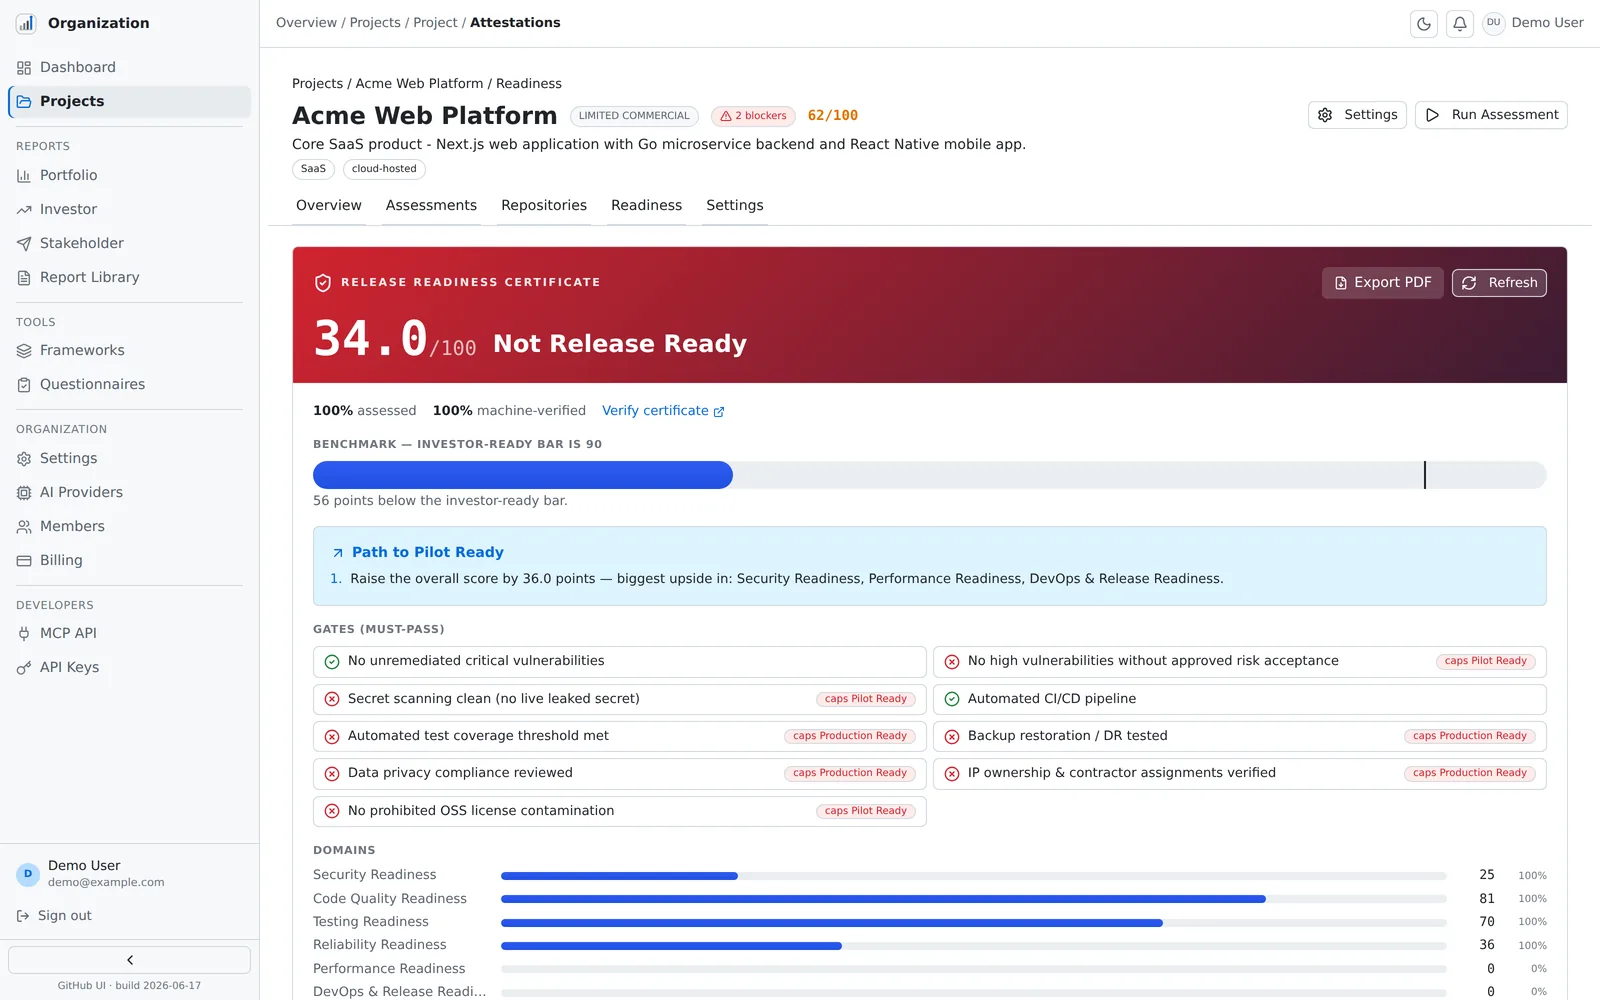
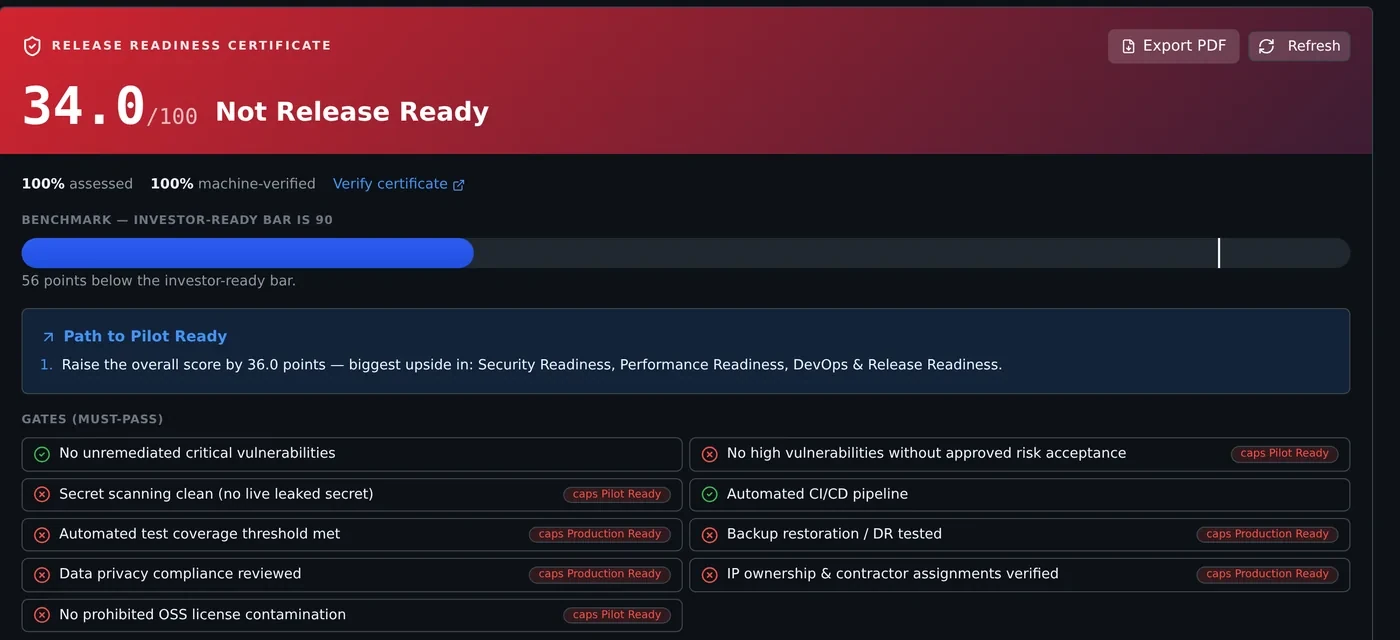
Comreadiness Release Readiness certificate: score with certified tier, benchmark against the investor-ready bar, path to the next tier, and must-pass gates with pass/fail state
Product screen · sample organisation datacomreadiness.com/verify
Frameworks
04
Specialist agents
30
Deterministic rules
500+
Model panel
Multi-LLM
Deliverables
12
Audit trail
End-to-end
Who it's for

One assessment. Three sides of the table.

The same evidence trail answers a different question depending on where you sit: buying, building, or accountable for the result.

For investors

Know which targets are actually real.

A first-pass technical screen on any target's GitHub, before you spend a partner's afternoon or an advisor's invoice on it.

  • Portfolio triage, side by side
  • Re-run quarterly to track the delta
  • Board- and LP-ready exports
<1 hrto an evidence-backed verdict
How the screen works
For founders

Walk in already knowing the score.

Run the same assessment an acquirer would on your own codebase. Fix what matters before the partner meeting; ignore the rest with receipts.

  • Self-DD before the raise
  • The acquirer's-eye view, early
  • A debt list that's actually triaged
Same rulesthey'll run on you
See what we measure
For team leaders

Give the board a defensible answer.

Engineering, security, and platform leads get an objective, repeatable read on readiness, with the evidence to back every number when someone pushes.

  • An onboarding map for new hires
  • Reconciled across multiple models
  • Audit trail for every claim
Every citetraceable to a control
Inside the method
How it works

From repository to decision, in three movements.

We instrument the technical-readiness portion of diligence so the partner spends their hour on the founder, not the codebase.

Phase 01, Collect

Connect.

Install the read-only GitHub connector (Personal Access Token, scoped to read). Link one repository or an entire organisation. We never clone or publish your source. Only bounded evidence excerpts are kept (never your full repository), and they're deleted with the assessment. Revocable in one click.

Read more
Phase 02, Reason

Assess.

We run 500+ deterministic rules and up to 30 AI specialist agents against the framework you choose. Every finding cites a control code; code-pattern findings additionally cite a file location (with a line range when the agent can pinpoint it). The rule layer is fully reproducible run-to-run.

Read more
Phase 03, Report

Decide.

Investor-grade report with executive summary, maturity matrix, blocker queue, and remediation workbook. Generate the signed Release Readiness certificate and share its public verify link, so anyone can check it's authentic without touching your code. Re-run quarterly to track movement against itself.

Read more
Inside the product

What you actually get.

Real product screens from a live assessment of a sample organisation, not mockups.

The assessment

Every finding cited, scored, and triaged.

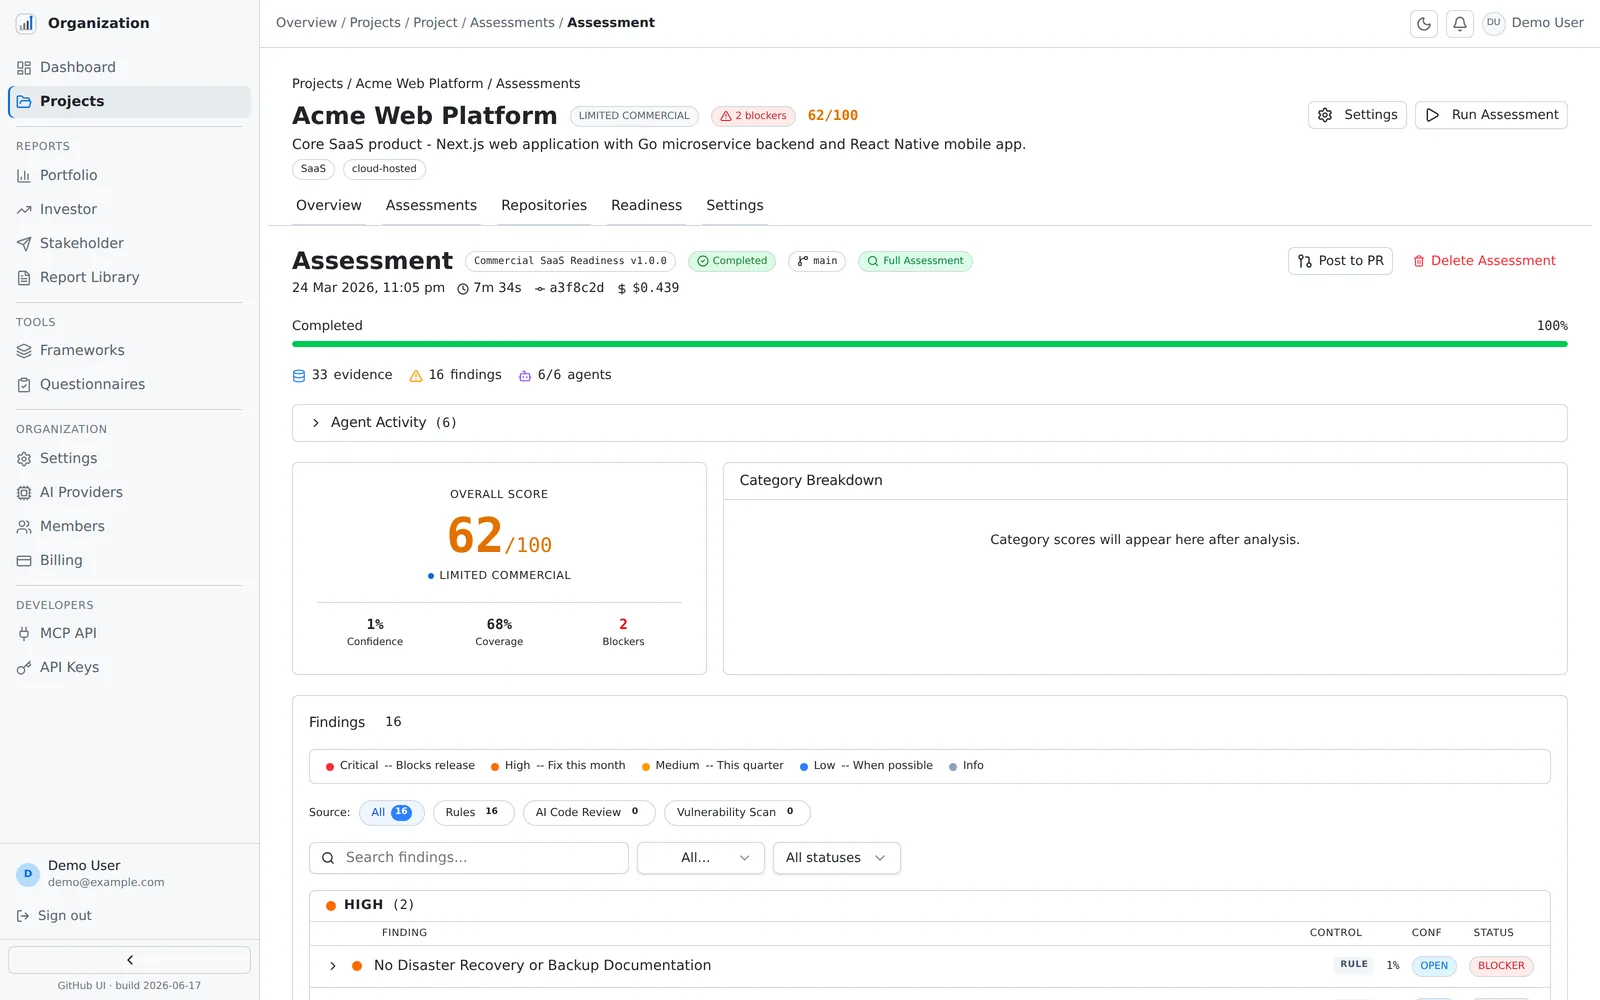
A completed run shows the overall score, evidence collected, and every finding grouped by severity, from release-blocking criticals down. Each finding cites the control it failed and, for code patterns, the file behind it.

  • 500+ deterministic rules, including language-idiomatic SAST for Python, JavaScript, Go, Java, C#, PHP, Ruby and Rust
  • Findings filter by source: rules, AI code review, vulnerability scan
  • Propose-only remediation: draft a fix PR for a finding; nothing is pushed without your approval
Comreadiness assessment results: overall score 62/100 with blockers, evidence and agent counts, and a findings table grouped by severity with control citations
Product screen · sample organisation data
The Release Readiness Index

A score that can't flatter you.

Ten weighted domains roll up into one certificate, but must-pass gates cap the certified tier, so a high average with a live blocker still reads Not Release Ready. Controls a machine can't verify (DR tests, pen tests, IP assignments) are covered by recorded human attestations, kept distinct from machine-verified evidence.

  • Benchmark against the investor-ready bar, with the gap in points
  • Path to the next tier: which gates and domains move the score most
  • Export the certificate as a print-ready PDF diligence pack
Release Readiness certificate: score with certified tier, must-pass gates with pass/fail state, benchmark bar against the investor-ready threshold, and per-domain scores
Product screen · sample organisation data
The public certificate

Verification anyone can run.

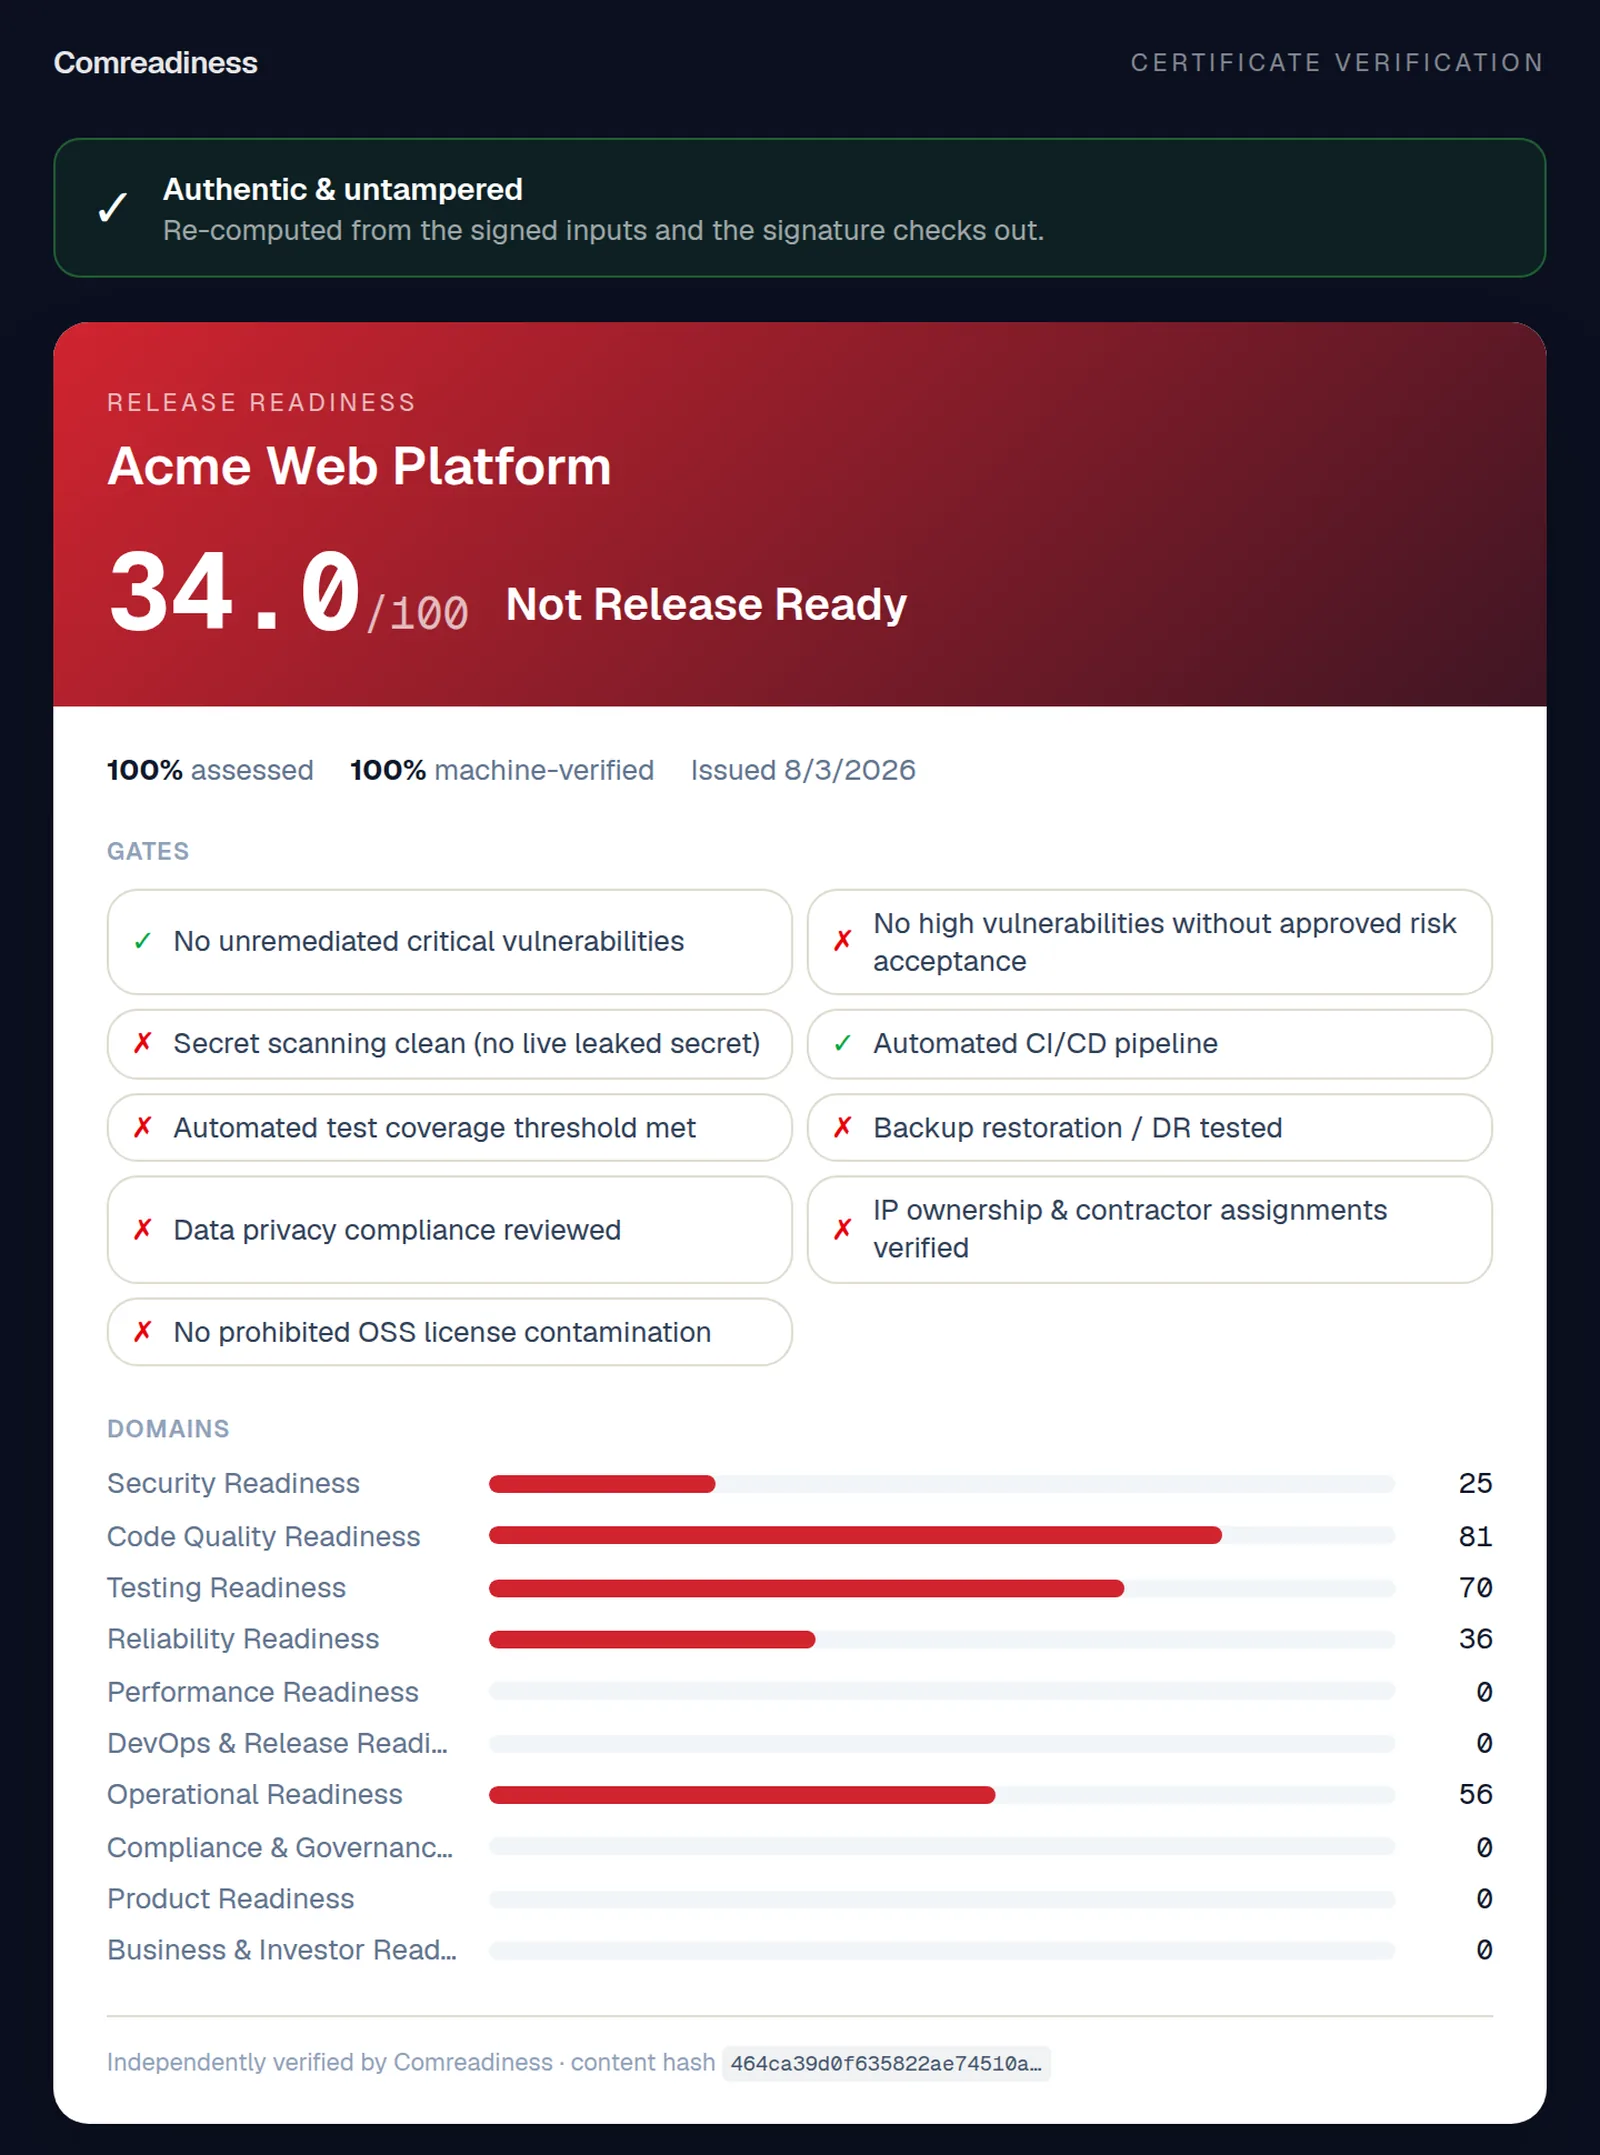
Every certificate carries a public verify link. The page recomputes the result from the signed inputs and checks the signature; edit a single displayed figure and verification fails. Share it with an investor, acquirer, or board without giving them access to anything else.

  • Signed and tamper-evident, with the content hash shown
  • No login required to verify; the link is the artifact
  • Shows gates, domains, and coverage, never your source
Public certificate verification page confirming the certificate is authentic and untampered, with gate results and per-domain scores
Product screen · sample organisation data
Frameworks

Four lenses. One source of truth.

Most tools generate output. We narrow it. Each framework is a structured rubric of controls, run by specialist agents against real evidence. Modular rule packs by language, framework, deployment target, or compliance regime.

+ 44 modular rule packs
  • FW.0126 controls
    Technical Due Diligence
    Architecture · Documentation · Testing maturity
    Investor / acquirer
  • FW.02102 controls
    Commercial SaaS
    Packaging · Onboarding · Multi-tenant isolation
    Launch readiness
  • FW.0324 controls
    Enterprise Release
    Governance · Rollback · Operational resilience
    Deployment readiness
  • FW.0419 controls
    Security Baseline
    IP & licensing · Secrets · Authorisation
    Posture & provenance
Assurance

We tell you how well we checked, not just what we checked.

Every tool in this category publishes a coverage number. Almost none publish how strongly each control was actually examined, which is the first thing a diligence lead asks. Each of our controls carries one of three assurance levels, and the level is set by what the check genuinely does.

Verified

The configuration or the repository's own measured history is read directly. If the control is absent, that absence is a real finding, not an inference.

Deployment and container configuration, release and maintenance history, contributor concentration.

Indicative

A strong signal in source, flagged for review rather than asserted. These checks can miss things, so they say so: they carry reduced confidence and are routed to human review instead of quietly moving a score.

Code-level security patterns, language and framework conventions, project-type expectations.

Declared

A document or configuration references the control. That evidences the subject was considered. It does not evidence the control is implemented, and it is excluded from the automated score for exactly that reason.

Certification-style clauses that require human attestation, such as governance and privacy commitments.

Mapped to the frameworks buyers actually name

447 controls crosswalked

Every control the platform runs is attributed to the standards a buyer, auditor or acquirer will ask about, so a finding arrives with the clause it belongs to rather than as an opinion.

FrameworkFocusControls
ISO 27001:2022Annex A controls reachable from source363
NIST SSDF (SP 800-218) v1.1The software development lifecycle framework300
CIS Controls v8Application security and configuration143
SOC 2 Type IITrust services criteria89
NIST CSF 2.0Identify, protect, detect75
OWASP ASVS 4.0Verification requirements19
CIS Docker BenchmarkContainer image and runtime hardening8
CIS Kubernetes BenchmarkPod security and workload isolation7
AWS Well-Architected Security PillarCloud infrastructure declared in IaC7
Microsoft Cloud Security BenchmarkAzure infrastructure declared in IaC6
CISA SBOM Minimum Elements (2026)Software bill of materials, the EU CRA baseline4

A control can map to more than one framework, so these do not sum to the total. Every control carries an assurance level and coverage is reported split by those levels in the product, so a figure is never quoted without saying how strongly it was checked.

Honest scope

What we replace. What we don't.

Restraint is the feature. Tools that promise everything decide nothing. We compress the technical-readiness portion of diligence and stop there. Knowing where the line is is what makes the signal worth trusting.

Inside scope

What we replace

  • First-pass technical screen on a target's GitHub
  • Architecture, security, ops, and code-quality review
  • Documentation, testing maturity, release governance
  • Reproducible rule findings with file path provenance (line range where available)
  • Cross-target comparison for portfolio triage
Outside scope

What we don't

  • Customer references and revenue / churn analysis
  • Penetration testing or live-system security work
  • Financial DD, legal review of customer contracts
  • Patent / IP search beyond connected source code
  • The judgement of an experienced operator at the table
Multi-model panel

Don't take one model's word for it.

A single model has a single bias. For a decision this consequential, run a panel: several LLMs assess the same evidence independently, and we reconcile them. Agreement is signal. Disagreement is where the real questions live.

How a panel reads
Anthropic Sonnet 5
Ready
OpenAI GPT-5
Split call
Google Gemini 2.5 Pro
Ready
Arbiter

Models agree the architecture is sound; they split on tenant isolation: GPT-5 flagged it a blocker, the others did not. The evidence (a shared DB schema with no row-level scoping) supports the stricter call. Verify before launch.

Illustration of the panel flow, not live output.

Independent verdicts

Pick the models: the latest managed Anthropic and OpenAI frontier models, or bring your own key (BYOK) for Gemini, DeepSeek, Mistral, or a self-hosted endpoint. Each one scores the same evidence on its own.

Consensus, and where it breaks

We line the verdicts up: where the models agree you can move; where they diverge, whether that is a score gap, a disputed blocker, or a finding only one model saw, we surface it precisely.

An arbiter that explains why

A final pass rationalises the disagreement: why the models differ, which call the evidence best supports, and the next step to settle it. The result is one reconciled verdict you can defend.

Never grading its own homework

If the evidence shows your code was predominantly built with one vendor's model, the AI review runs on the other vendor's: code written with Anthropic models is examined by an OpenAI model, and vice versa. When attribution is ambiguous or the counter-model isn't available, the run says so instead of pretending.

Managed models run under your plan's cost cap. Bring-your-own keys are encrypted at rest and run on your own quota, including private, self-hosted models for sovereign deployments.

Recently shipped

The product moved. Here is exactly where.

Everything on the left runs today and shows up in an assessment you can execute yourself. Everything on the right is decided and not built. We keep the two lists separate because a roadmap that quietly absorbs the shipped column is how software gets sold twice.

Shipped
  • Software supply chain

    Whether a bill of materials is produced at all, whether it describes what actually ships rather than what the manifests intended, whether releases are signed, and whether the components underneath are genuinely pinned. Aligned to the 2026 minimum elements published by CISA with seventeen international partner agencies, which the EU Cyber Resilience Act already makes a commercial requirement.

  • Build provenance

    A bill of materials says what is in the release. Provenance says how it came to be, which is what lets a customer confirm the binary they received corresponds to the source they were shown.

  • Where the code actually moves

    The files being changed most, cross-referenced with who is changing them, whether they are tested, and whether they sit in security-sensitive territory. The output is not a metric, it is a sentence about a specific file: this one changes constantly, one person understands it, and it handles authentication.

  • Engineering process, proved from behaviour

    Whether review is required and enforced for everyone including administrators, whether approvals survive later changes, whether ownership is defined for the areas that matter, and whether the review queue is keeping up. Configuration audits report that review is enabled. Enabled is a weaker claim than enforced.

  • Your own scanners, read as evidence

    Where a repository already runs deeper analysis, its results are ingested and scored rather than ignored or duplicated. Reimplementing that badly would be an expensive way to be worse.

  • The AI dependency

    Not how much of the code was AI-assisted, which we already reported, but what the running product depends on: whether the model dependency is declared anywhere, whether its version can change underneath you, whether untrusted text can reach it, and whether the calls are bounded in cost and time.

  • Eight languages, read the way each one is written

    Java and Spring, C# and .NET, PHP and Laravel, Ruby and Rails, and Rust join Python, JavaScript and Go. A generic scanner finds generic problems. These read each ecosystem's own failure modes: what deserialization means in Java, what unserialize means in PHP, and for Rust the questions that actually apply once memory safety is the default, including whether the advisory database is ever consulted at all.

  • The fix, not just the finding

    Where an assessment finds a required artefact missing, 26 production-grade files are available to close it: security policy, disclosure process, CI and release pipelines, architecture and setup documentation, operational runbook, incident response, disaster recovery, data retention. Telling a founder their runbook is missing is worth less than handing them one.
Next
  • Run it from your own pipeline

    Today an assessment starts here. It should be able to start from a pull request in your repository, or from a command line, without an account existing first. That is the next piece of work.

  • Parity across hosting providers

    Several of the newest checks read signals that only one provider currently exposes. Where a signal is unavailable the control reports as unassessed rather than passing, and closing that gap is queued.

  • Independently verifiable release artifacts

    Signed, published build outputs so a recipient can verify integrity without taking our word or yours for it.

  • Deeper evaluation of AI-bearing systems

    Model behaviour testing sits beyond what static evidence can reach today. It is on the roadmap, and it is not claimed anywhere in the product until it exists.

Deliverables

Twelve artefacts. One run.

Every assessment ships distinct deliverables, each built for a different audience: partners, founders, engineers, LPs, auditors. All of it led by a signed, independently verifiable certificate.

Verifiable certificate

A signed Release Readiness certificate with a public verify link. An investor confirms the score is authentic and untampered without re-running anything, and it can't be doctored after the fact.

SBOM & licence risk

A full software bill of materials with every dependency's licence classified as permissive, copyleft, or prohibited, so GPL/AGPL contamination surfaces before a deal does, not after.

GenAI-code exposure

How much of the codebase shows AI-authorship signals, and whether that AI use is governed. The provenance and IP question every 2026 acquirer now asks.

Key-person risk

Contributor concentration and bus-factor analysis from commit history: how much of the codebase only one person understands, before that person resigns mid-diligence.

Executive summary

One page. Board-ready. Plain English score, the three things to fix, the three things working.

Remediation workbook

Quick wins and effort estimates. The list a CTO can hand to their team on Monday morning.

Technical findings

Every finding in full: severity, file path, the evidence behind it, and the standards clause it maps to. The detail an engineer needs to disagree with us, which is the point.

Coding-agent action script

The findings rewritten as instructions a coding agent can execute, with the fix templates inlined. Hand it to Claude Code or Cursor instead of re-typing the workbook.

Audit trail and provenance

Who ran what, when, and against which commit, plus a processing record for every assessment. Prompt content is never stored. This is the artefact an auditor asks for.

Machine-readable export

The whole assessment as JSON: scores, findings, evidence and control attribution. Drop it in a data room or pipe it into your own reporting.

Path to the next tier

Not just the score. The gates currently capping your tier, the point gap, and the domains ranked by how much closing them would move it.

Printable diligence pack

The certificate, gates, domain scores, remediation path and licence appendix on one printable page, with the public verify URL on it. Print to PDF and attach it to the data room.

Every artefact is saved to the report library, so a deliverable can be re-opened and re-exported later without re-running the assessment.

Trusted because

The defaults we ship with.

Read-only by design

Read-only GitHub connector. We never clone or publish your source; we retain only bounded evidence excerpts (capped per file and per repository), deleted with the assessment.

No model training

Your code and findings are never used to train AI models, ours or the providers'.

Auditable evidence

Every finding cites a control; code-pattern findings cite a file location (with a line range when the agent can pinpoint it). No opaque AI scores.

From the founder

Why this exists.

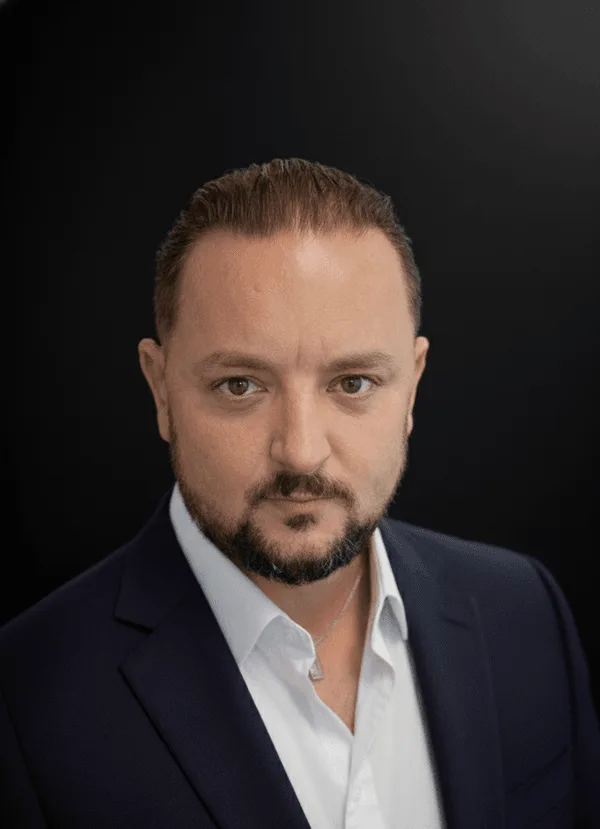
I'm Jason Agnew. I run Belton IT Nexus, a New Zealand managed IT and cyber-security company, and I've spent years on the technical side of deals watching the same thing happen: good teams walk into due diligence blind. The first time they see their codebase through an acquirer's eyes is when a deal or a raise is already on the line, and by then every surprise is expensive.

Comreadiness is the check I wanted to hand them months earlier: what a buyer would find, with the evidence to back it, and a certificate anyone can verify without taking our word for it.

Jason Agnew
Jason Agnew
Founder
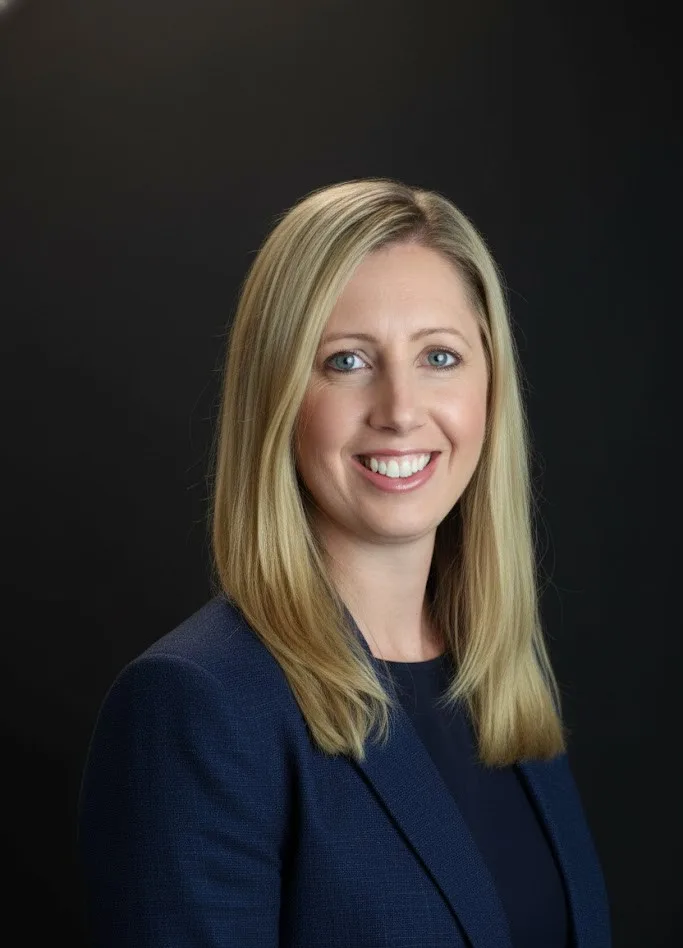
Amy Agnew
Amy Agnew
Co-founder
Pricing

Priced by portfolio size.

Three subscription tiers, plus Sovereign on the roadmap: a BYOC (bring your own cloud) deployment for environments where source can't touch a third-party LLM. Pricing isn't released yet; waitlist members see launch pricing first. AI cost is BYOK today: bring your own Anthropic or OpenAI key, capped per assessment so spend stays predictable.

See full pricingNeed a self-hosted deployment with a configurable AI endpoint? Talk to us about Sovereign, scoped per engagement.
Let's talk

One repo. Under an hour. Walk away knowing.

Bring any repository you have read access to. We'll run a live assessment with you. We won't be the loudest tool in your inbox. We'll be the one that earns the second meeting.